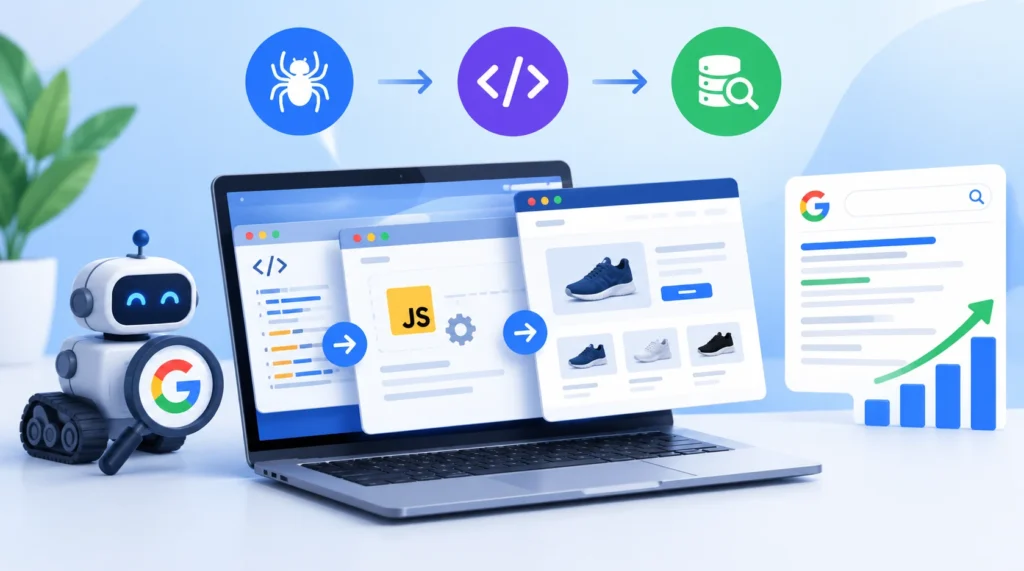
JavaScript is an important part of modern websites. It powers interactive navigation, product filters, live search, dynamic content, single-page applications and many of the features users now expect from a website.
For SEO, however, the important question is not simply whether a website uses JavaScript.
The real question is:
Can search engines discover, crawl, render and understand the important content and links that JavaScript produces?
A JavaScript-powered website can work perfectly for users while still creating problems for search engines. Important content may appear only after JavaScript executes, internal links may not use crawlable URLs, canonical tags may change during rendering or a page may visually show an error while the server continues returning a successful response.
JavaScript SEO focuses on identifying and preventing these problems.
This guide explains how JavaScript SEO works, how Google processes JavaScript pages, the difference between common rendering methods, the issues SEOs should look for and how to audit and improve a JavaScript-powered website.
What Is JavaScript SEO?
JavaScript SEO is a branch of technical SEO focused on ensuring that search engines can successfully crawl, render, understand and index websites that rely on JavaScript.
It covers the relationship between JavaScript and important search signals such as page content, internal links, metadata, canonical tags, robots directives, structured data, URLs and HTTP responses. The purpose is not to remove JavaScript from a website.
Instead, JavaScript SEO makes sure that modern website functionality does not prevent search engines from accessing the information they need to understand a page.
Google describes JavaScript processing through three main stages: crawling, rendering and indexing. Google Search also runs JavaScript using an evergreen version of Chromium.
For an SEO professional, this creates one central question:
Does the search engine receive and understand the same important content, links and technical signals that the user receives?
If not, the website may have a JavaScript SEO problem.
Why Does JavaScript Matter for SEO?
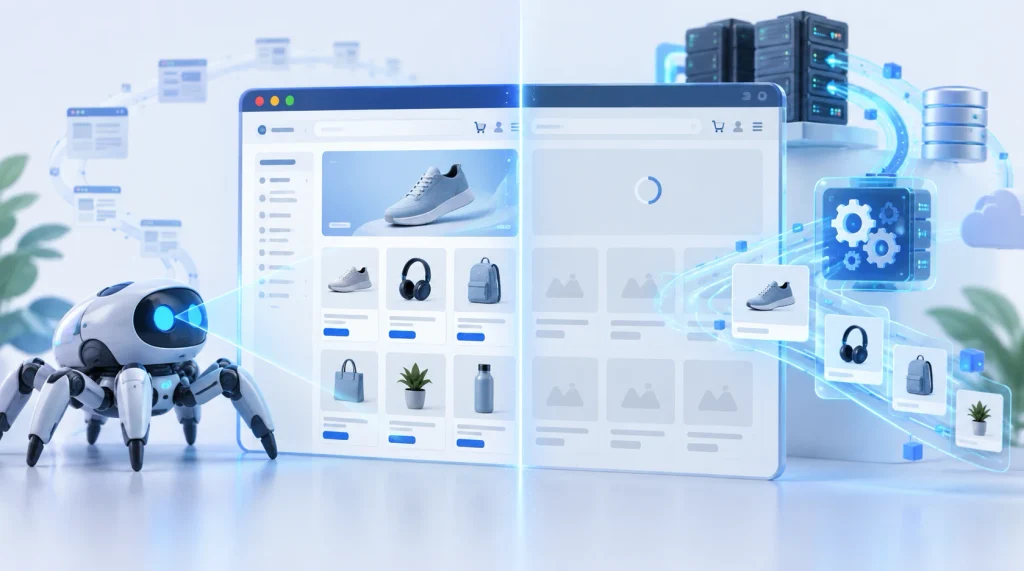
On a traditional server-rendered page, much of the information search engines need may already exist in the HTML returned by the server.
A crawler can request the URL and immediately encounter the page heading, main copy, navigation, internal links and other important elements.
JavaScript can make this process more complex because some parts of the page may not exist until scripts execute.
Consider an ecommerce category page. The server might initially return the header, footer and category name, while JavaScript later retrieves the products from an API and inserts product names, links, images, prices and filters into the page.
For a visitor using a modern browser, this can appear completely seamless. From an SEO perspective, however, it creates an important distinction:
What exists in the initial HTML, and what becomes available only after rendering?
JavaScript itself is not inherently harmful to SEO. Problems occur when the implementation makes important content, links or technical signals inaccessible, inconsistent or unreliable for search engines.
How Does Google Process JavaScript?
Understanding how Google processes JavaScript is fundamental to JavaScript SEO.
Google documents three main phases:
Crawling → Rendering → Indexing.
Crawling
Googlebot first needs to discover a URL.
It may find pages through internal links, external links, XML sitemaps or URLs it has previously discovered.
Googlebot then requests the URL and checks whether crawling is allowed. If a URL or required resource is blocked, Google may not be able to process the page as expected.
Google also parses the initial HTML response for links before rendering takes place. This is one reason strong internal linking remains important on JavaScript websites.
Rendering
After crawling, Google can queue an eligible page for rendering. During rendering, Google’s systems use Chromium to execute JavaScript and create the rendered version of the page. JavaScript may add or modify content, links, navigation, images, metadata and other page elements.
Google then examines the rendered HTML and can discover additional crawlable links that were inserted by JavaScript.This is why examining only the visual page is not enough during a JavaScript SEO audit.
SEOs often need to compare:
Initial HTML → Rendered HTML
to understand exactly what JavaScript changes.
Indexing
Once Google has processed the page, it can use the rendered HTML when considering the page for indexing. This makes the final rendered output important.
If critical content does not exist in the rendered HTML available to Google, that content cannot be indexed. Google’s current documentation specifically recommends checking rendered HTML when troubleshooting JavaScript content.
Can Google Crawl and Index JavaScript?
Yes. Google can execute JavaScript and process JavaScript-generated content. The idea that Google simply cannot understand JavaScript is outdated. However, Google’s ability to execute JavaScript does not mean that every JavaScript implementation is automatically SEO-friendly.
A successful process still depends on Google being able to discover the URL, access the required resources, render the page correctly and find the expected content and technical signals. Instead of asking:
Can Google render JavaScript?
A more useful SEO question is:
Can Google reliably render and understand this particular JavaScript implementation?
That should be verified through testing rather than assumed.
Initial HTML vs Rendered HTML
Comparing initial and rendered HTML is one of the most useful techniques in JavaScript SEO.
What Is Initial HTML?
Initial HTML is the document the server sends when the URL is first requested. You can normally inspect it using View Page Source in your browser. It shows what is available before client-side JavaScript changes the page.
What Is Rendered HTML?
Rendered HTML represents the page after the browser has processed the initial document and executed JavaScript. You can examine the rendered DOM through browser developer tools. The differences between the two can reveal where your SEO dependencies exist.
| SEO Element | Initial HTML | Rendered HTML | What It May Indicate |
|---|---|---|---|
| H1 | Present | Present | Little or no rendering dependency |
| Main Copy | Missing | Present | Content depends on JavaScript |
| Product Links | Missing | Present | Discovery depends on rendering |
| Canonical | URL A | URL B | Potential canonical conflict |
| Robots Directive | Index | Noindex | Major indexability change |
| Structured Data | Missing | Present | Structured data depends on rendering |
A difference does not automatically mean something is wrong. It tells you which elements depend on JavaScript and therefore require closer testing.
What Is JavaScript Rendering?
Rendering is the process of turning HTML, CSS, JavaScript and related resources into the final webpage. Different websites use different rendering strategies. For SEO, the most important approaches are client-side rendering, server-side rendering and static generation.
| Rendering Method | Where Content Is Primarily Generated | Main SEO Consideration |
|---|---|---|
| Client-Side Rendering (CSR) | Browser | Greater reliance on JavaScript execution |
| Server-Side Rendering (SSR) | Server | Important HTML can be available immediately |
| Static Site Generation (SSG) | Build time | HTML exists before the request |
| Hybrid Rendering | Multiple locations | Different templates may behave differently |
| Hydration | Server/static HTML enhanced by JS | HTML arrives first, JavaScript adds interactivity |
There is no single rendering method that is automatically correct for every website. The right implementation depends on functionality, content freshness, performance, infrastructure and user requirements.
From an SEO perspective, the key requirement is that important content and signals remain reliably accessible.
Client-Side Rendering and SEO
With client-side rendering, the browser does much of the work required to build the page. The initial response may contain only limited content or an application shell. JavaScript then executes, retrieves additional information and populates the page.
This can create a greater dependency on rendering.
For example, if the initial HTML contains an empty application container and the primary service content appears only after JavaScript executes, Google needs the rendered version to fully understand that content.
CSR is not automatically bad for SEO.
The important step is checking whether essential content, internal links, metadata, canonical signals and structured data appear correctly after rendering.
Server-Side Rendering and SEO
With server-side rendering, the server generates the HTML before sending the page to the browser. This means important content can be present immediately when Googlebot requests the URL. Server-side rendering can reduce dependence on client-side execution for the initial content.
Google’s current JavaScript SEO guidance still describes server-side or pre-rendering as a useful approach because it can improve accessibility and speed for users and crawlers, while not every bot can execute JavaScript.
SSR, however, does not automatically make a website SEO-friendly.
A server-rendered website can still have poor internal linking, duplicate pages, incorrect canonical tags, indexation problems or performance issues. Rendering is only one part of technical SEO.
Static Site Generation and SEO
Static Site Generation (SSG) creates HTML during the build process rather than creating the entire page when someone requests it.
This approach can work particularly well for content that does not need to change constantly, including blog posts, documentation and marketing pages. Because the HTML already exists, important content can be delivered without requiring the browser to generate everything client-side.
JavaScript can then enhance the page with interactive functionality.
Hydration and Hybrid Rendering
Modern websites do not always fit neatly into either CSR or SSR.
A website might server-render important HTML and then use JavaScript to hydrate the page and add interactivity. Another site might statically generate articles, server-render product pages and use client-side rendering for account areas.
This is why SEO audits should focus on what each page template actually produces, rather than judging a website only by the framework it uses.
CSR vs SSR vs SSG: Which Is Better for SEO?
There is no universal winner.
SSR can reduce dependency on client-side execution. SSG can provide highly accessible pre-generated pages. CSR can also work when implemented correctly.
The better question is:
Which approach makes the website’s important content, URLs and SEO signals consistently accessible while meeting the site’s technical and user requirements?
That is a more useful framework than choosing a rendering method purely because it is perceived as being “better for SEO.”
Common JavaScript SEO Problems
JavaScript SEO problems can be difficult to spot because the website may look completely normal in a browser. The issues usually appear when there is a difference between what users experience and what search engines can discover or render.
Important Content Is Missing
Important page content may be inserted entirely through JavaScript. This can include product descriptions, service content, headings, prices, reviews or category text. If important content does not exist in the initial source, check whether it appears correctly in rendered HTML.
The question is not simply whether JavaScript created the content. The question is whether search engines can access the completed result.
Internal Links Are Not Crawlable
Internal links help search engines discover pages and understand the relationships between them. Google generally expects crawlable links to use an <a> element with an href attribute. Google also confirms that links dynamically inserted with JavaScript can be crawled when they use the correct anchor markup.
For example: <a href=”/technical-seo/”>Technical SEO</a> is straightforward for crawlers.
An element that behaves like a link only because of a JavaScript event, without a valid href, is less reliable for discovery. This becomes especially important for navigation menus, product cards, pagination, filters and related-content sections.
Important JavaScript Resources Are Blocked
JavaScript and CSS resources may be required to produce the page Google needs to see. If important resources are blocked from crawling, rendering can be affected. Google states that it won’t render JavaScript from blocked files or blocked pages. Review robots.txt and other access controls when investigating missing rendered content.
Canonical Tags Change During Rendering
Canonical tags help search engines understand the preferred version of similar URLs. Problems can occur when one canonical exists in the original HTML and JavaScript changes it to another URL after rendering.
Google recommends specifying canonicals in HTML where possible. If JavaScript is used, Google advises keeping the JavaScript-generated canonical consistent with the value in the original HTML. Conflicting canonical signals should therefore be investigated.
Robots Directives Change With JavaScript
JavaScript can add or modify robots meta directives. This requires particular care
Google notes that when it encounters a noindex directive, rendering may be skipped. Attempting to use JavaScript to remove an initial noindex may therefore not work as intended. If a page should be indexed, avoid returning noindex in the original HTML and expecting JavaScript to reverse it later.
Metadata Is Incorrect After Client-Side Navigation
JavaScript can update titles and meta descriptions. This is common in single-page applications.
Problems occur when different URLs accidentally share the same title, a previous page’s metadata remains after navigation or important metadata fails to update. Check important URL states individually instead of assuming the application manages metadata correctly.
Lazy-Loaded Content Is Not Accessible
Lazy loading can reduce unnecessary resource usage and improve performance. It becomes an SEO issue when important content is loaded only after an interaction that a search crawler may not perform.
When testing lazy-loaded elements, verify what exists in the rendered HTML rather than relying solely on what appears when you manually scroll or click.
Infinite Scroll Limits Content Discovery
Infinite scroll is common on ecommerce categories, job websites, property listings and content feeds. The user can continue scrolling while JavaScript loads additional items. For search engines, however, important products or pages still need discoverable URLs.
If additional content is available only after scrolling and there is no crawlable navigation path, search engines may not discover everything efficiently.
JavaScript Creates Incorrect HTTP Status Behaviour
HTTP status codes tell search engines what happened when a URL was requested. Some JavaScript applications visually display a “Page Not Found” message while the server still returns 200 OK.
This can create a soft-404 situation.
Google recommends using meaningful HTTP status codes and provides specific guidance for client-side applications where error handling happens after the initial response.
Structured Data Does Not Render Correctly
Structured data can be created with JavaScript. Google supports JavaScript-generated JSON-LD, but the implementation should still be validated after rendering.
Check the final result rather than assuming structured data exists because the application was configured to generate it.
How to Audit JavaScript SEO
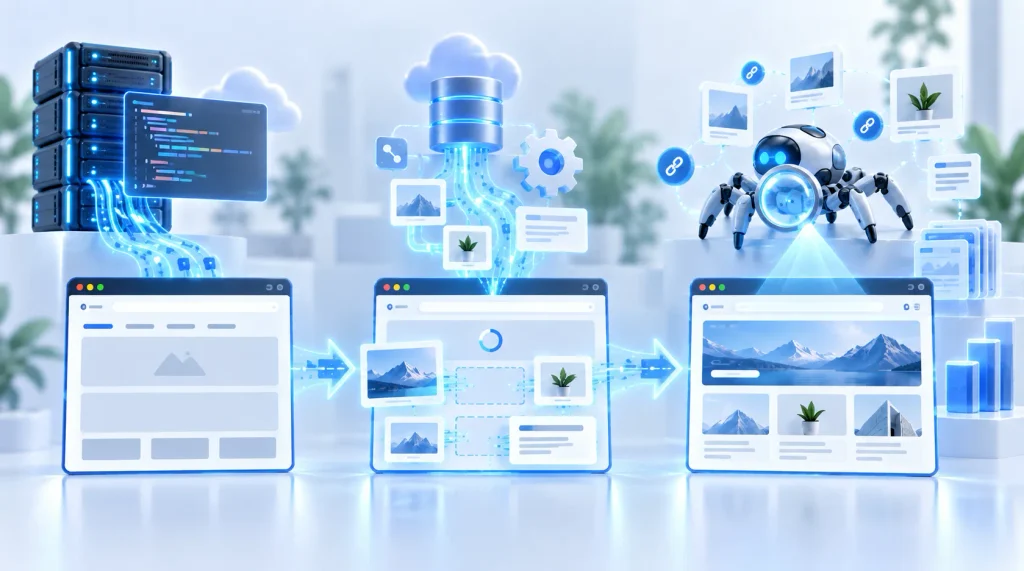
A JavaScript SEO audit should answer three questions:
What does the server initially return?
What changes after JavaScript executes?
What can Google ultimately access and understand?
Step 1: Inspect the Initial HTML
Open an important URL and use View Page Source.
Check whether the title, H1, primary content, internal links, canonical URL, robots directives and structured data are present. This gives you a baseline before client-side JavaScript changes anything.
Step 2: Inspect the Rendered DOM
Open browser Developer Tools and inspect the same page. Search for the same SEO elements. If content exists in the rendered DOM but not in the source HTML, JavaScript is responsible for adding it. That is not automatically a problem. It simply identifies a rendering dependency.
Step 3: Compare Initial and Rendered HTML
Look specifically for differences that can change search-engine understanding. A missing paragraph that appears after rendering may be expected. A canonical that changes to another URL may require immediate investigation.
Prioritise differences involving content, links, indexability and canonicalisation rather than treating every DOM change as an SEO issue.
Step 4: Use Google Search Console
Use URL Inspection for representative URLs.
Check whether Google can crawl the page, which canonical it recognises and whether the expected content appears in the processed page.
Google also recommends URL Inspection and the Rich Results Test when troubleshooting JavaScript and checking rendered HTML.
Step 5: Crawl With JavaScript Rendering Enabled
For larger websites, manual testing is not enough. Tools such as Screaming Frog and Sitebulb can crawl websites with JavaScript rendering enabled.
Compare rendered and non-rendered crawling results for important attributes such as titles, headings, internal links, canonicals, robots directives and indexable content.
Large differences can reveal where JavaScript is materially affecting SEO.
Step 6: Check JavaScript Errors
Use the browser console to identify JavaScript errors. A failed API call or broken component can become an SEO problem when it prevents important content or navigation from being rendered.
Do not assume a page is healthy simply because most of the layout appears correctly.
Step 7: Test Multiple Templates
Do not audit only the homepage.
A JavaScript implementation can behave differently across service pages, product pages, categories, articles, pagination, search results and faceted navigation.
Test representative URLs from all important templates.
How to Fix Common JavaScript SEO Issues
The correct solution depends on the actual problem rather than on JavaScript itself.
| Problem | Potential SEO Impact | Fix Direction |
|---|---|---|
| Important content fails to render | Content may be unavailable | Fix rendering or provide critical HTML earlier |
| Links lack crawlable URLs | Poor page discovery |
Use valid <a href> links
|
| Required resources are blocked | Incomplete rendering | Allow required resources to be crawled |
| Canonical changes unexpectedly | Conflicting canonical signals | Keep canonical implementation consistent |
Initial page contains noindex
|
Page may remain excluded |
Do not rely on JS to remove initial noindex
|
| Infinite scroll has no crawlable path | Deeper content may be missed | Provide discoverable URLs/navigation |
Missing page returns 200
|
Soft-404 risk | Use meaningful HTTP status behaviour |
| JavaScript error stops content | Missing content or links | Fix application/runtime errors |
The important principle is to identify the actual failure first. Changing an entire site from client-side rendering to server-side rendering, for example, would be excessive if the actual problem is simply a set of non-crawlable navigation links.
JavaScript SEO Best Practices
A strong JavaScript SEO implementation makes important content and technical signals reliable rather than merely hoping that crawlers will reconstruct the page correctly.
Critical content should be easy to access. Important links should use real URLs. Canonicals and robots directives should remain consistent. Required resources should not be unnecessarily blocked, and important URL states should return meaningful HTTP responses.
Rendered output should also be tested after significant development changes. JavaScript frameworks, libraries and website architecture can change quickly. What worked correctly before a redesign, deployment or migration may behave differently afterwards.
The core principle is simple:
Test the output search engines receive, not just what the website was intended to produce.
JavaScript SEO for React, Next.js, Vue and Angular
Framework names alone do not determine SEO performance. A React website can use heavy client-side rendering or be implemented with server-rendered content. Next.js can use multiple rendering strategies. Vue can be combined with Nuxt, and Angular applications can also be built in different ways.
The relevant SEO questions remain the same.
Can search engines discover every important URL?
Does the expected content appear after rendering?
Are internal links crawlable?
Are titles, canonicals and robots directives correct?
Are meaningful status codes being returned?
The correct approach is therefore to audit the output rather than judge the framework. Framework-specific subjects such as React SEO or Next.js SEO can become deeper standalone topics, but they all sit underneath the broader JavaScript SEO principles covered here.
JavaScript SEO and Website Performance
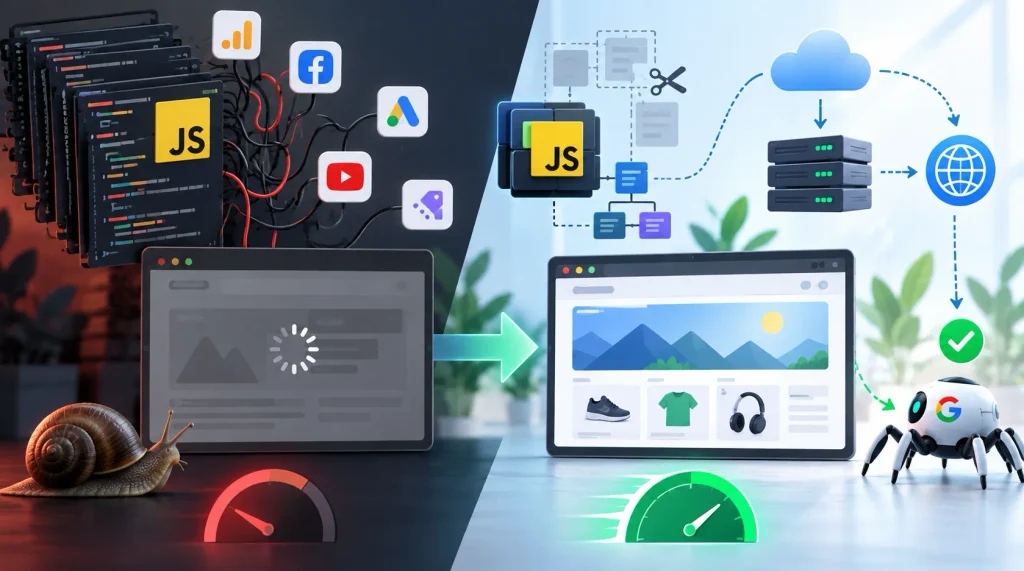
JavaScript can also affect website performance. Large script bundles, unnecessary third-party code and heavy client-side processing can increase the amount of work a browser has to perform. This can affect how quickly users can interact with the website and may contribute to poor page-experience metrics.
Performance optimisation can include reducing unused JavaScript, limiting unnecessary third-party scripts, splitting large bundles, improving data requests and delaying non-critical work. However, JavaScript performance and JavaScript SEO are not exactly the same subject.
Performance is one part of the wider technical picture alongside crawlability, rendering, indexability and website architecture.
JavaScript SEO Checklist
Before considering an important JavaScript template search-friendly, check the following:
- Main content is available in rendered HTML.
- Important URLs can be discovered through crawlable links.
- Internal links use valid <a href> markup.
- Required JavaScript and CSS resources are accessible.
- Important pages have stable URLs.
- Titles are correct after rendering.
- Canonical tags remain consistent.
- Robots directives match the intended indexability.
- Missing pages and redirects return meaningful responses.
- Structured data is present and valid after rendering.
- Lazy-loaded content remains accessible.
- Infinite-scroll content has a crawlable discovery path.
- Important content does not require user-only interactions.
- JavaScript errors are not preventing content from loading.
- Initial and rendered HTML have been compared.
- Important URLs have been tested through Google Search Console.
- Representative website templates have been tested rather than only the homepage.
- JavaScript rendering is included in technical SEO crawling where appropriate.
A failed check does not automatically mean a page cannot rank, but it shows where further investigation may be needed.
Frequently Asked Questions About JavaScript SEO
Is JavaScript Bad for SEO?
No. JavaScript itself is not bad for SEO. Problems occur when implementation choices make important content, links or technical signals difficult for search engines to access or interpret.
The correct question is whether the JavaScript implementation produces a crawlable, renderable and indexable website.
Can Google Crawl JavaScript Websites?
Yes, Google can crawl JavaScript-powered websites and uses Chromium during rendering. However, URLs and required resources still need to be accessible, and important content should be checked in the rendered result.
Can Google Index JavaScript-Generated Content?
Yes, provided the content becomes available in the rendered HTML Google can process. Google states that content not visible in rendered HTML cannot be indexed.
Does Google Execute JavaScript?
Yes, Google Search runs JavaScript using an evergreen version of Chromium as part of its rendering process.
Is Server-Side Rendering Better for SEO?
Server-side rendering can reduce reliance on client-side JavaScript for important initial content, but that does not make it universally superior.
The best implementation depends on the website’s functionality, architecture, content and performance requirements. SEO should evaluate the accessibility and consistency of the final output.
What Is the Difference Between Crawling and Rendering?
Crawling involves discovering and requesting URLs and their resources.
Rendering involves processing the page and executing JavaScript so dynamically generated content can become available. The rendered result can then contribute to Google’s indexing process.
How Can I See What Google Sees on a JavaScript Page?
Start with Google Search Console’s URL Inspection tools. You can also compare View Page Source with the rendered DOM in browser developer tools and use a JavaScript-capable SEO crawler when auditing larger websites.
Can JavaScript Affect Internal Linking?
Yes, Google generally crawls links when they use an <a> element with a valid href attribute. Links inserted dynamically with JavaScript can also be crawlable when they use this structure correctly.
Does JavaScript Affect SEO Performance?
It can. JavaScript can affect crawlability, rendering, internal link discovery and page performance depending on how it is implemented. The presence of JavaScript alone, however, is not an SEO problem.
Final Thoughts
JavaScript SEO is not about avoiding modern website technology. It is about ensuring that the technology does not create unnecessary barriers between your website and search engines.
For SEOs, the most useful way to approach JavaScript is through the complete processing journey:
Discovery → Crawling → Initial HTML → JavaScript Rendering → Rendered HTML → Indexing
Then verify what actually happens at each stage.
A page can look perfectly normal to a user while its source, rendered output or technical signals tell search engines something different. Comparing initial HTML against rendered HTML, testing crawlable links, reviewing indexability and checking representative templates can reveal problems that a normal visual review would miss.
That is why JavaScript SEO has become an important part of modern technical SEO.
At Clickmasters SEO Agency UK, SEO is at the core of what we do. Our SEO specialists work across technical SEO, crawling, indexation, site architecture and performance to identify problems that can limit organic search visibility.
If your JavaScript-powered website is experiencing crawling, rendering or indexing issues, explore our SEO services or speak with the Clickmasters team to discuss the technical problems affecting your site.